Kyrie Chen
Where scaling laws meet the open road.
I build training and inference systems for large models, and I write down what I learn. 49 technical notes and 19 travel essays so far, most of them in Chinese.
How a large model gets trained, in 8 parts.
From the data contract you lock before the first step to the evaluation that points back at the data. Each station is one article.

Pretraining
How the next-token objective moves through one step, and what to check first when the loss spikes.
Read part 2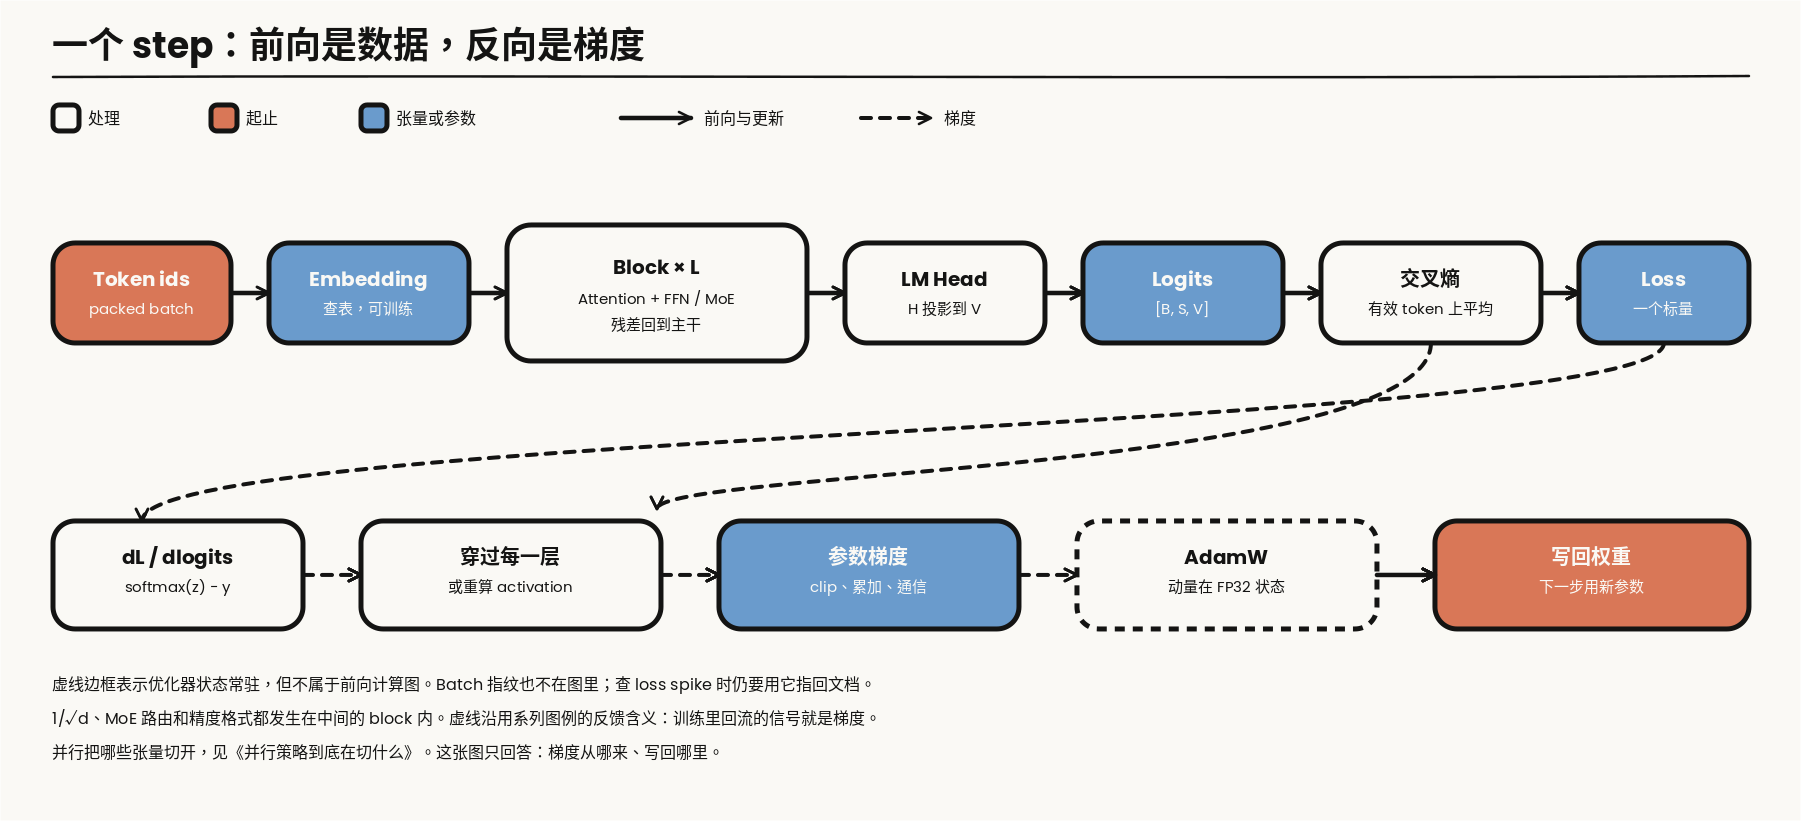
Mid-training
The learning rate is falling and the data mix is changing. Which one earned the gain?
Read part 3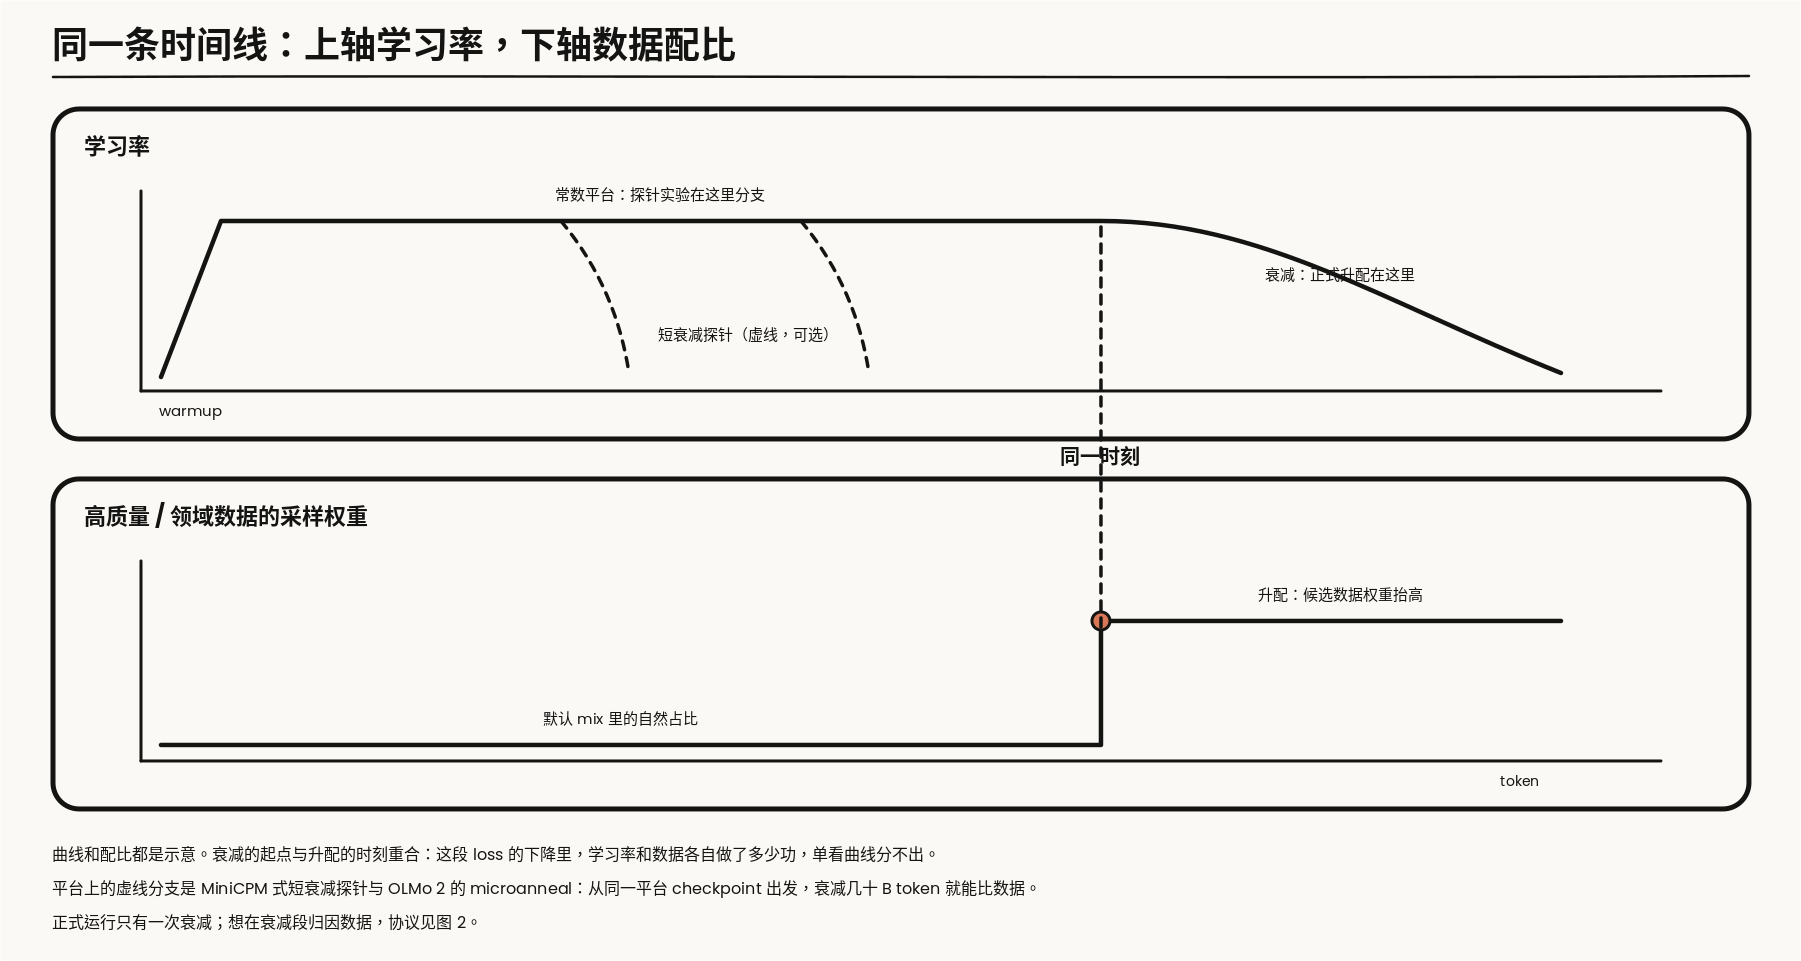
SFT
Supervision moves from every token to some tokens, and the loss mask draws the line.
Read part 4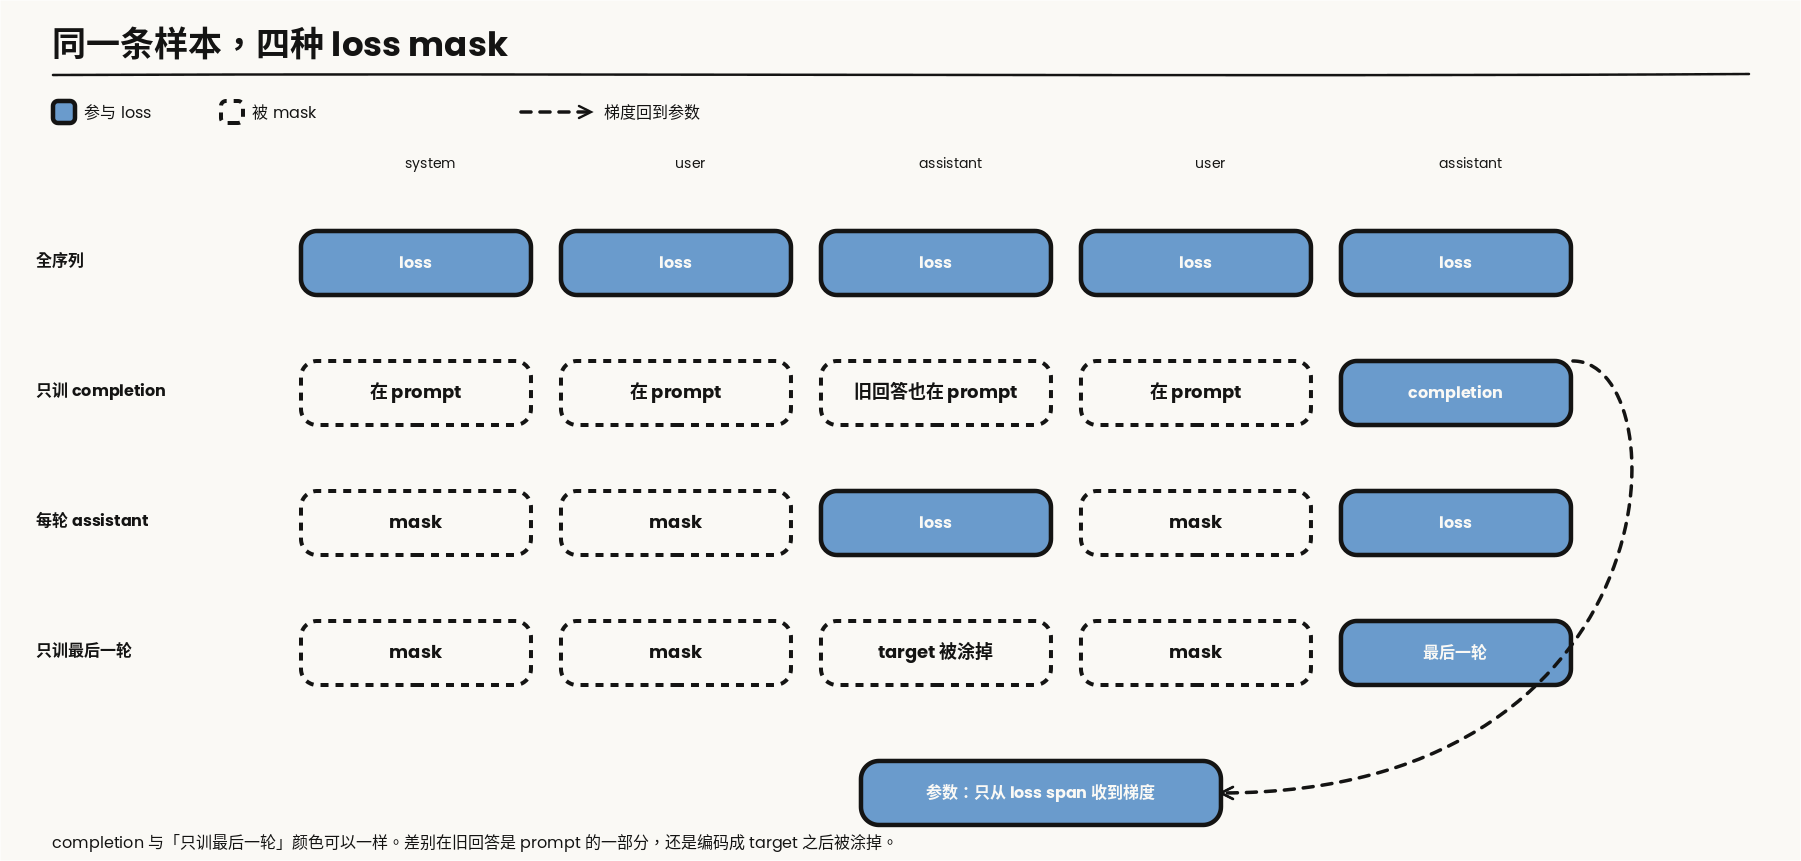
Preference alignment
Four models are in the room. Which ones score, and which ones update?
Read part 5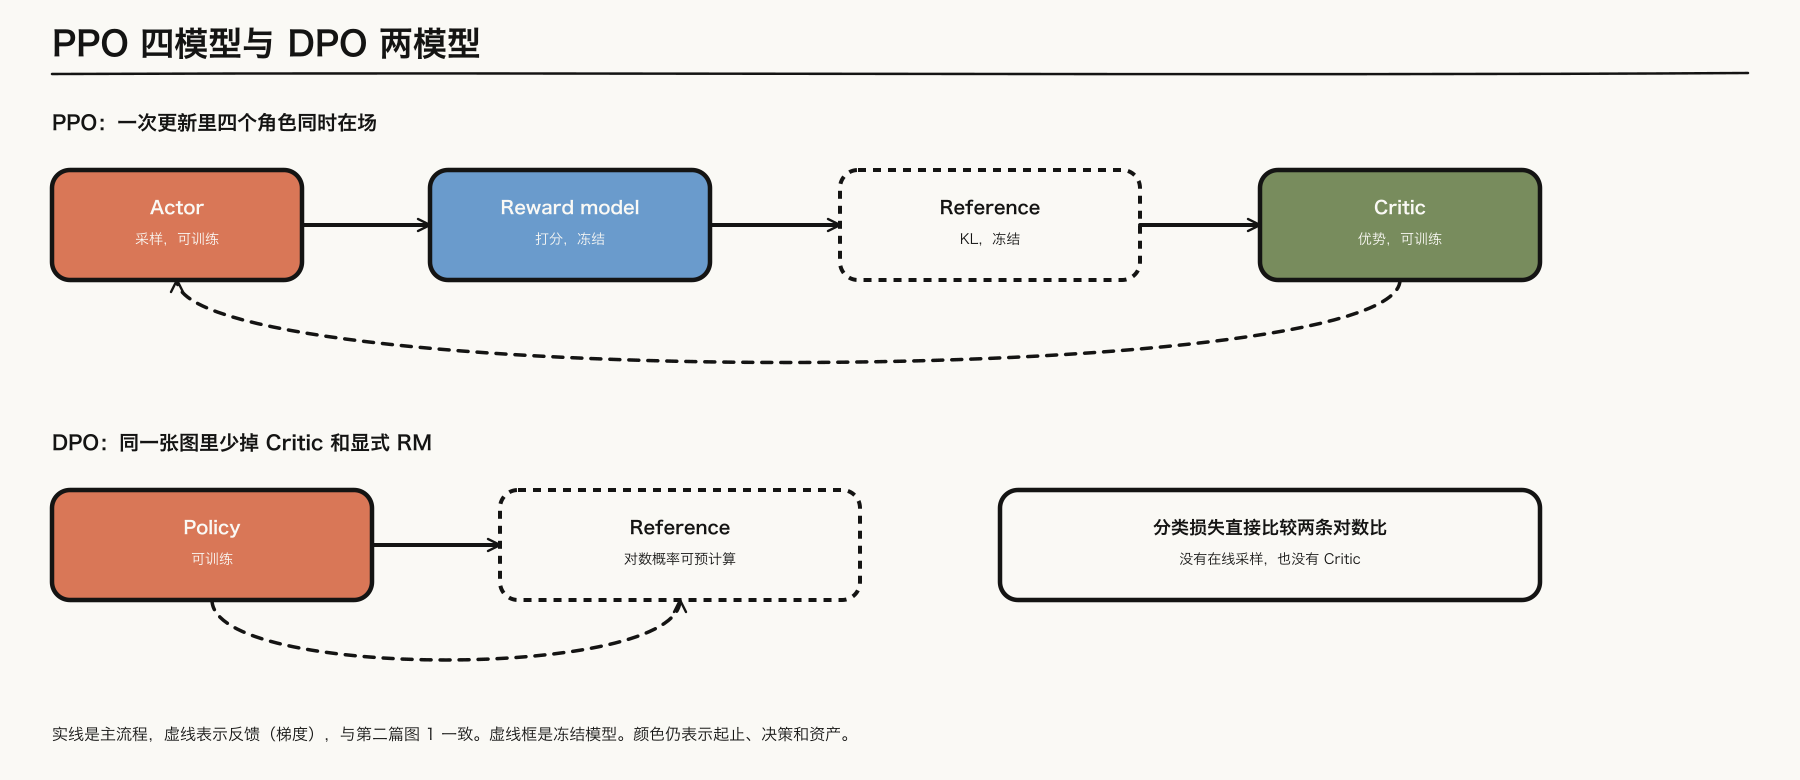
Reasoning RL
Rewards can now be checked by rules. Three ways training still gets out of hand.
Read part 6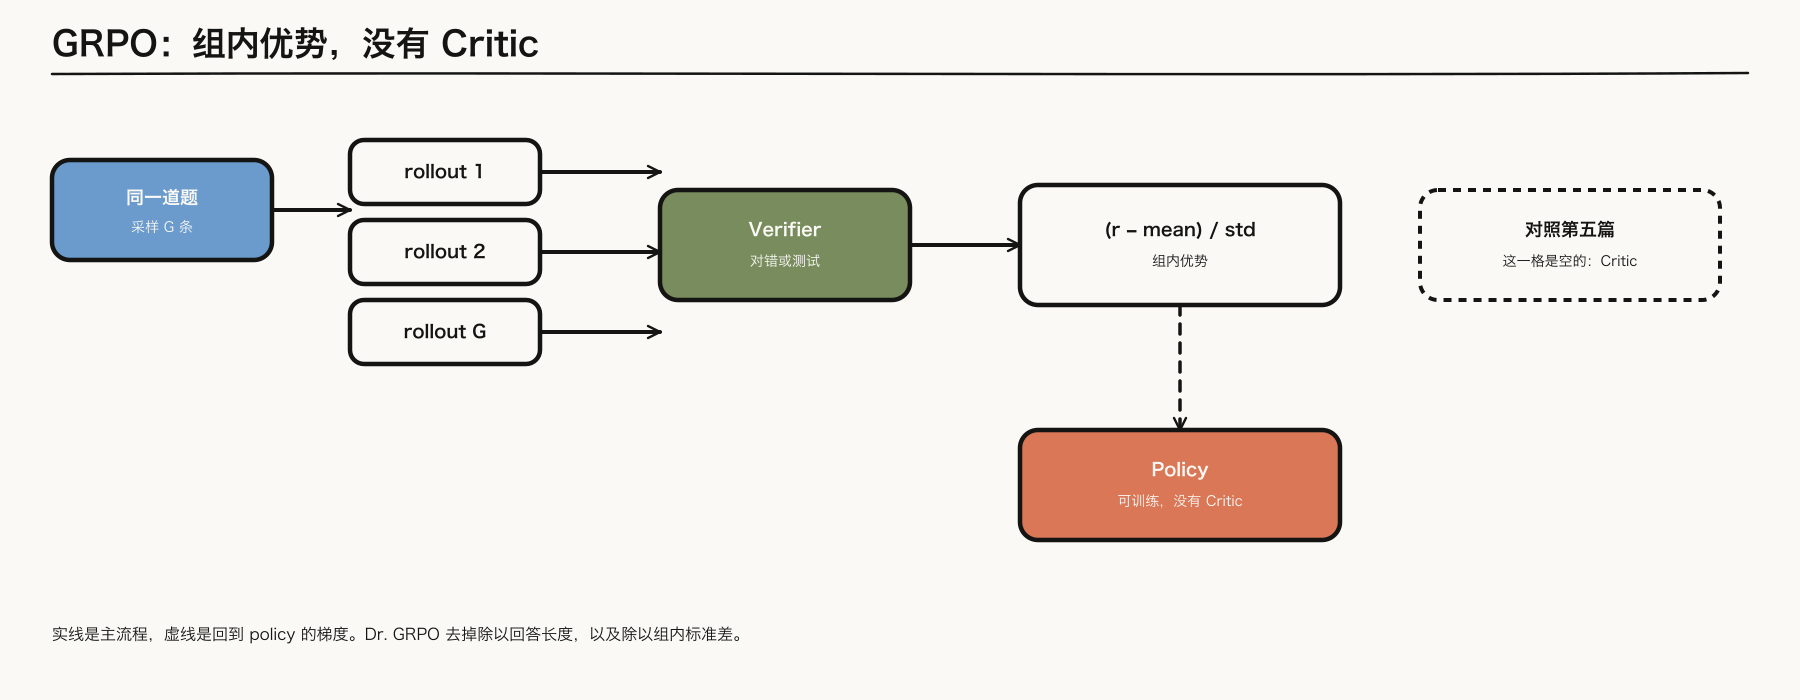
Agentic training
The reward waits at the end of a trajectory. Which tokens does the gradient reach?
Read part 7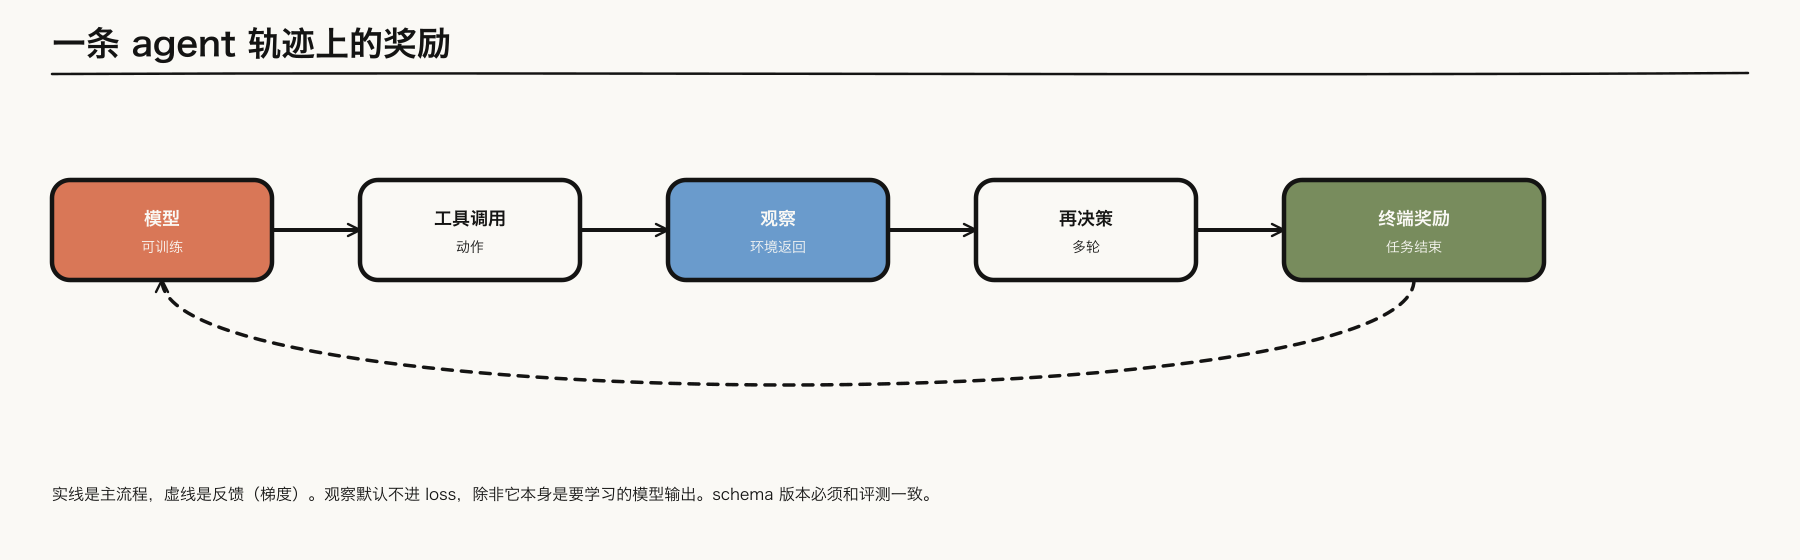
Distillation and evaluation
Moving the capability into a smaller model, and making scores point back at the data.
Read part 8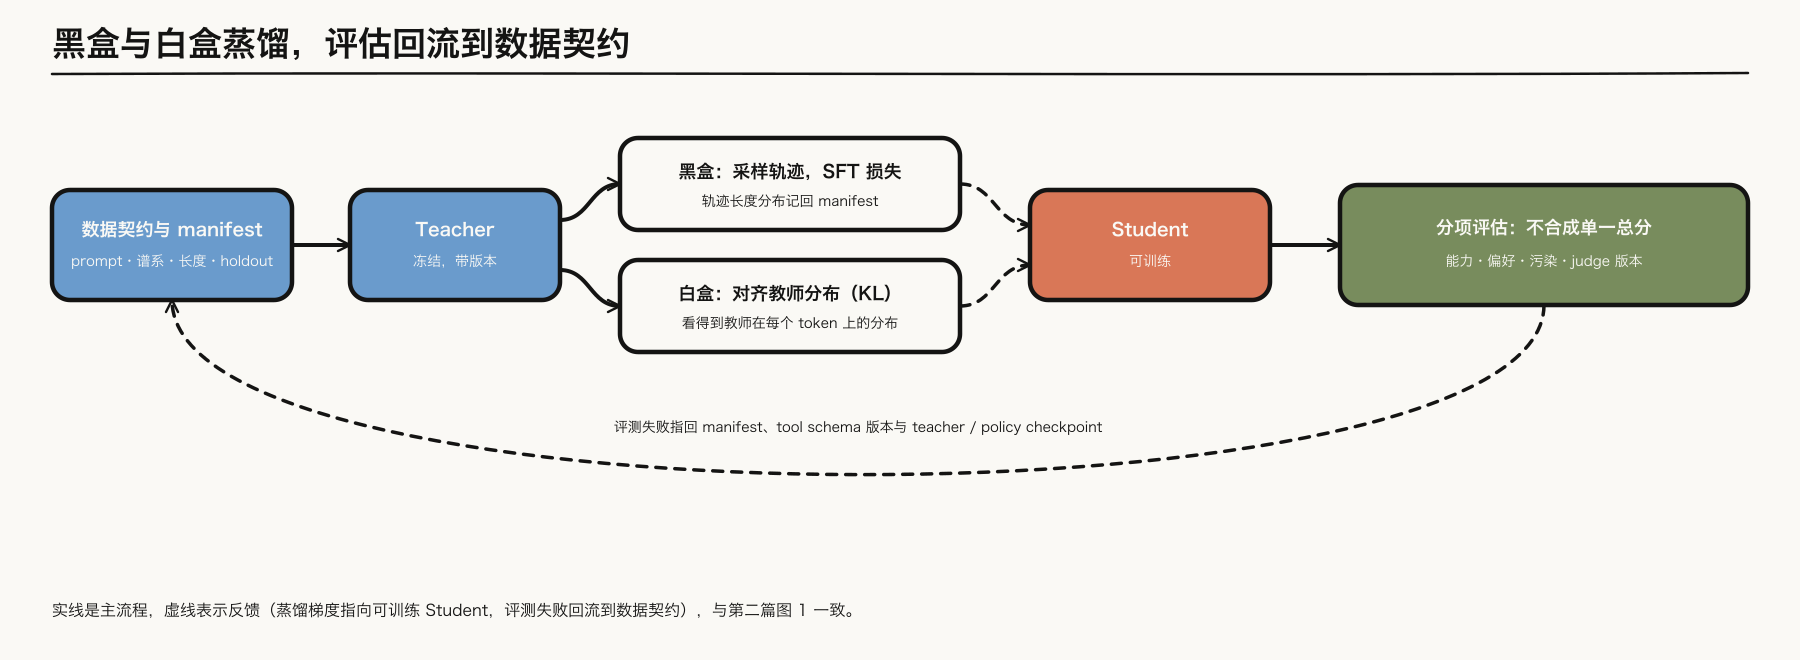
And the open road.
19 travel essays, from China's north-west to the Apennines. Drag the photos sideways.